Speech & audio
Transcripts, timestamps, speaker metadata, intent and language labels, accent information and noise tags.
Example annotation
00:01.20 — 00:03.85
“Set a reminder for tomorrow.”
Intent Set reminder Language English
Global data collection, annotation and validation for speech, vision and multimodal AI systems.
Your collection, annotation and validation — planned together, delivered to your specification.
Explore our capabilitiesSpeech technology Smart devices Computer vision Multimodal AI
From the first participant to the final validation, we connect the work that makes custom datasets possible.
 A voice. A language. A real-world context.
Capture the way people actually speak. Build a collection around the languages, accents, phrases and environments that matter to your system.
Thoughtful recruitment. Consistent capture. Image and video datasets built around the conditions your technology needs to understand.
Define your collectionA dataset becomes useful when its meaning is clear. Turn raw recordings and visual captures into consistent, structured information.
Transcripts, timestamps, speaker metadata, intent and language labels, accent information and noise tags.
“Set a reminder for tomorrow.”
Bounding boxes, landmarks, segmentation, keypoints, attributes, tracking and event labels.
A connected workflow, built around your technical specification and acceptance criteria.
Translate your requirements into participant profiles, screening criteria and a recruitment plan.
Set the scripts, equipment and collection conditions around your intended model use.
Apply labels, transcripts and metadata using a project-specific annotation guide.
Review quality, coverage and consistency against agreed acceptance criteria.
Package accepted data, annotations and supporting documentation in the formats you need.
Explore the possibilities for your next dataset. Every project is designed around your model, participants and collection requirements.
Shape your projectLanguage and accent coverage for speech recognition, conversational systems and model evaluation.
Language mix / Speaker profiles / Acoustic conditionsParticipant-led capture for computer vision and biometric technology development.
Capture protocol / Device setup / Participant criteriaTarget phrases, natural variations and device interactions for voice-enabled products.
Phrase design / Background noise / Device contextConnected speech, image, video and contextual data for systems that work across modalities.
Synchronized capture / Shared metadata / ValidationGood data starts with people: participants who bring real-world variety, collection teams who guide the process, and reviewers who make every detail count.
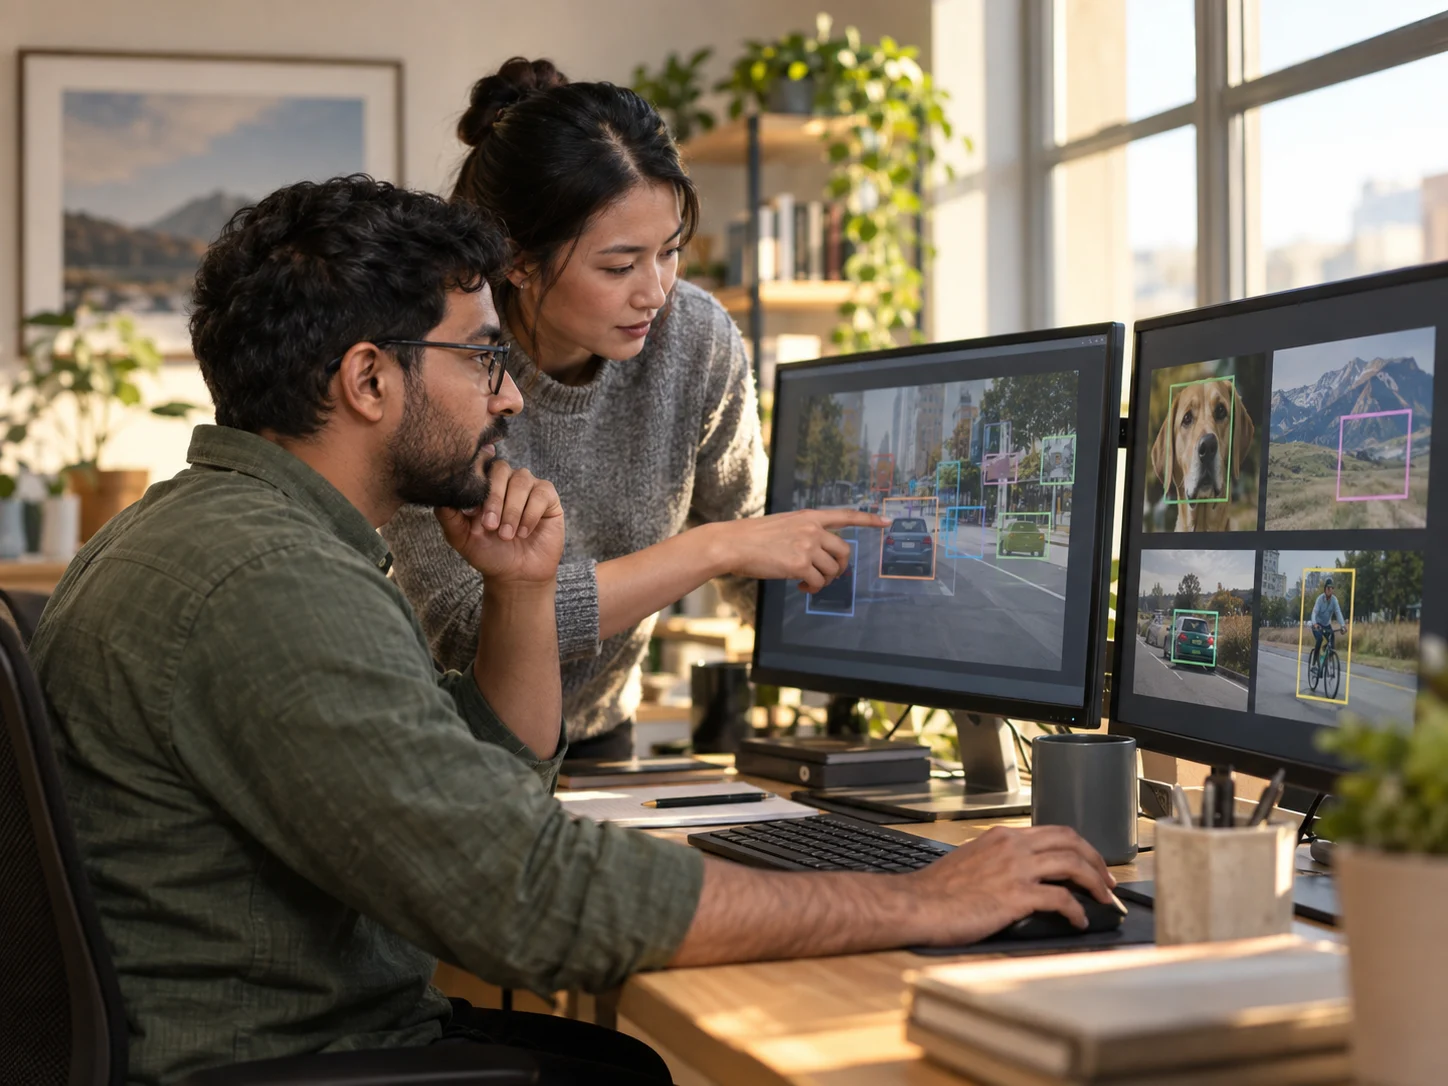
Illustrative imagery representing our services.
Recruitment and collection organized around the markets and languages your project requires.
Clear collection protocols, annotation guidance and agreed output formats.
Validation, consistency checks and a defined path for review and rework.
Adapt participant criteria, environments and workflows to your dataset needs.
Bring us your challenge. We’ll shape the participants, collection and quality standards around what your model needs.